Reinforcement Learning from AI Feedback (RLAIF): A Practical Guide to Scaling Alignment
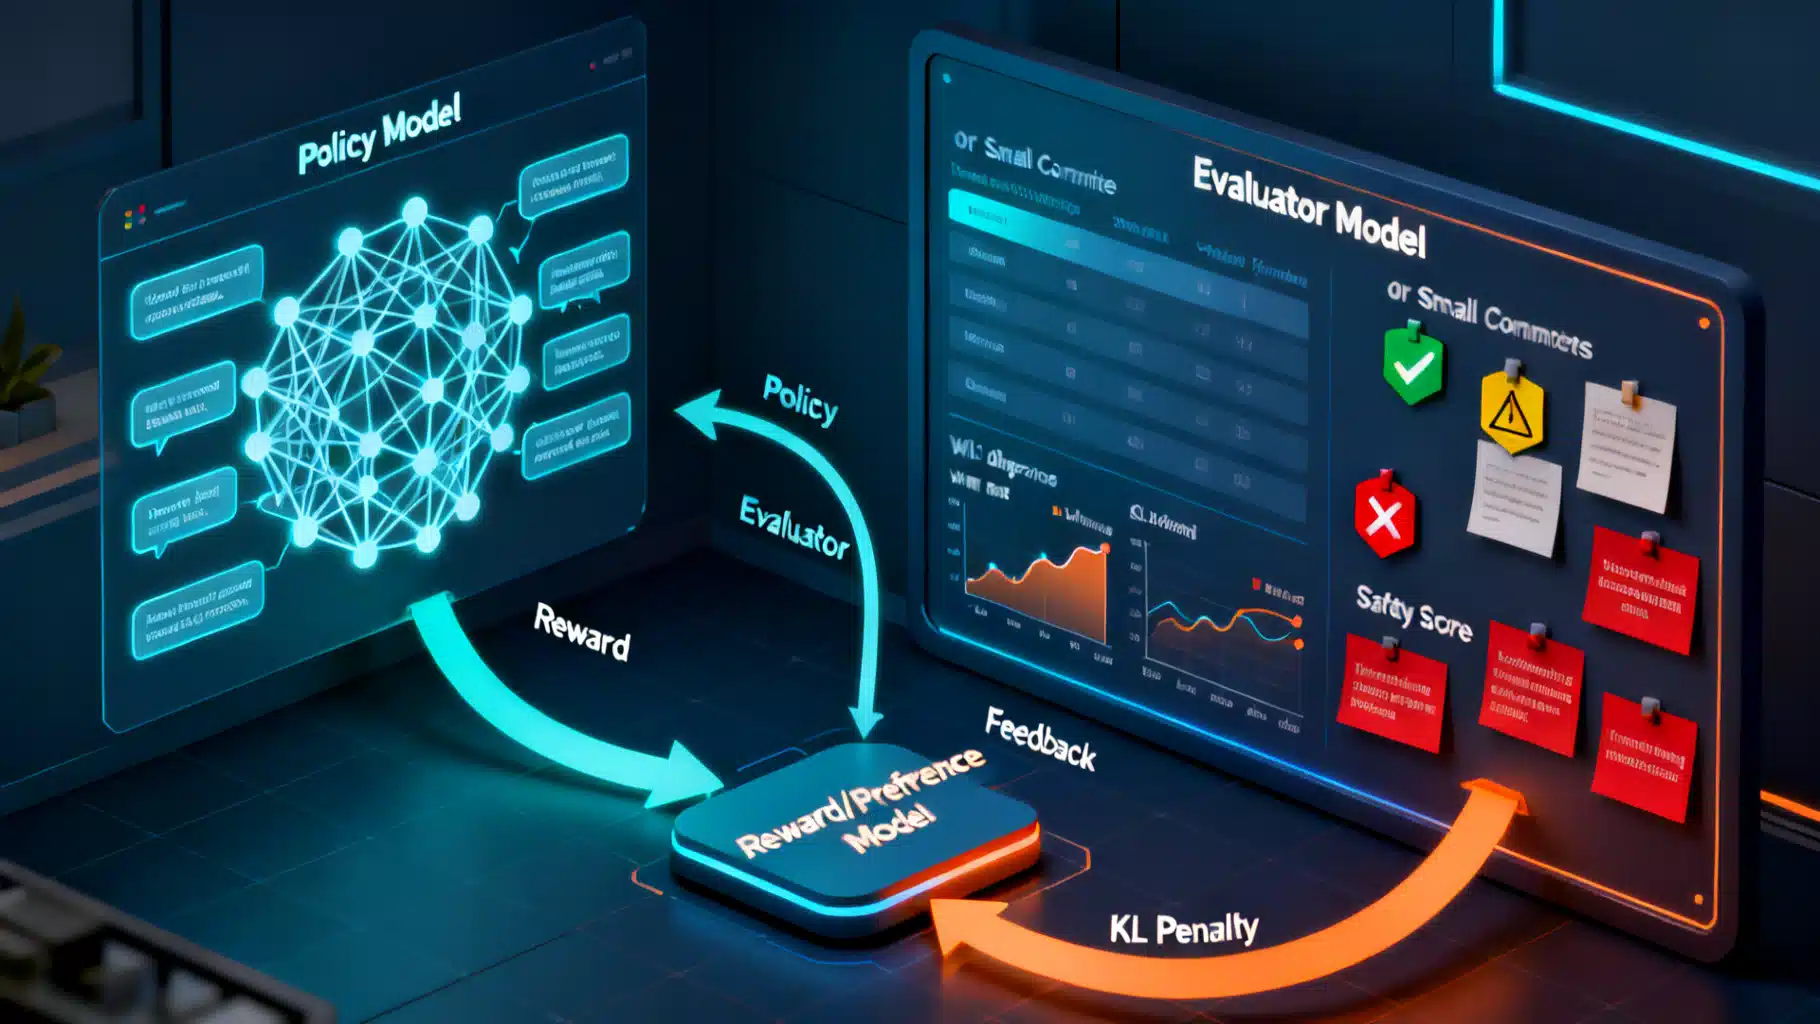
A practical guide to Reinforcement Learning from AI Feedback (RLAIF): how it works, key algorithms, design choices, pitfalls, and evaluation.
Learn how Constitutional AI aligns models using explicit principles, self-critique, and AI feedback, with recipes, code, and evaluation tips.
A clear, practical guide to RLHF—how human preferences train models, the pipeline, pitfalls, and modern variants like DPO and RLAIF.
A step-by-step guide to preparing high-quality datasets for LLM fine-tuning, from sourcing and cleaning to formats, safety, splits, and evaluation.
A practical, end-to-end guide to reducing AI hallucinations with data, training, retrieval, decoding, and verification techniques.